Abstract
Visual Autoregressive (VAR) modeling has attracted attention for its coarse-to-fine generation via next-scale prediction. However, higher scale resolutions lead to rapid token growth and substantially increased latency. Existing methods accelerate the late high-resolution stages by reusing converged tokens, but may discard high-frequency details in unupdated regions. To address this challenge, we propose PruneVAR, a training-free VAR acceleration framework that reduces redundant model computations without decreasing token inputs to preserve fine-grained texture coherence. Our approach is motivated by the finding that the redundancy in VAR transitions from stage-level stability to layer-wise functional overlap across the multi-scale generation process. Based on this insight, we introduce a corse-to-fine layer pruning strategy. Specifically, we first prune all layers at specific stages by skipping model forward while restoring pruned outputs using cached image increments from previous scale steps. As generation proceeds to higher resolutions, we pre-identify redundant layers by analyzing the overlap of core update regions and skip only these layers in the late stages. Experiments show that PruneVAR achieves up to 2x speedup while maintaining competitive visual quality.
Method
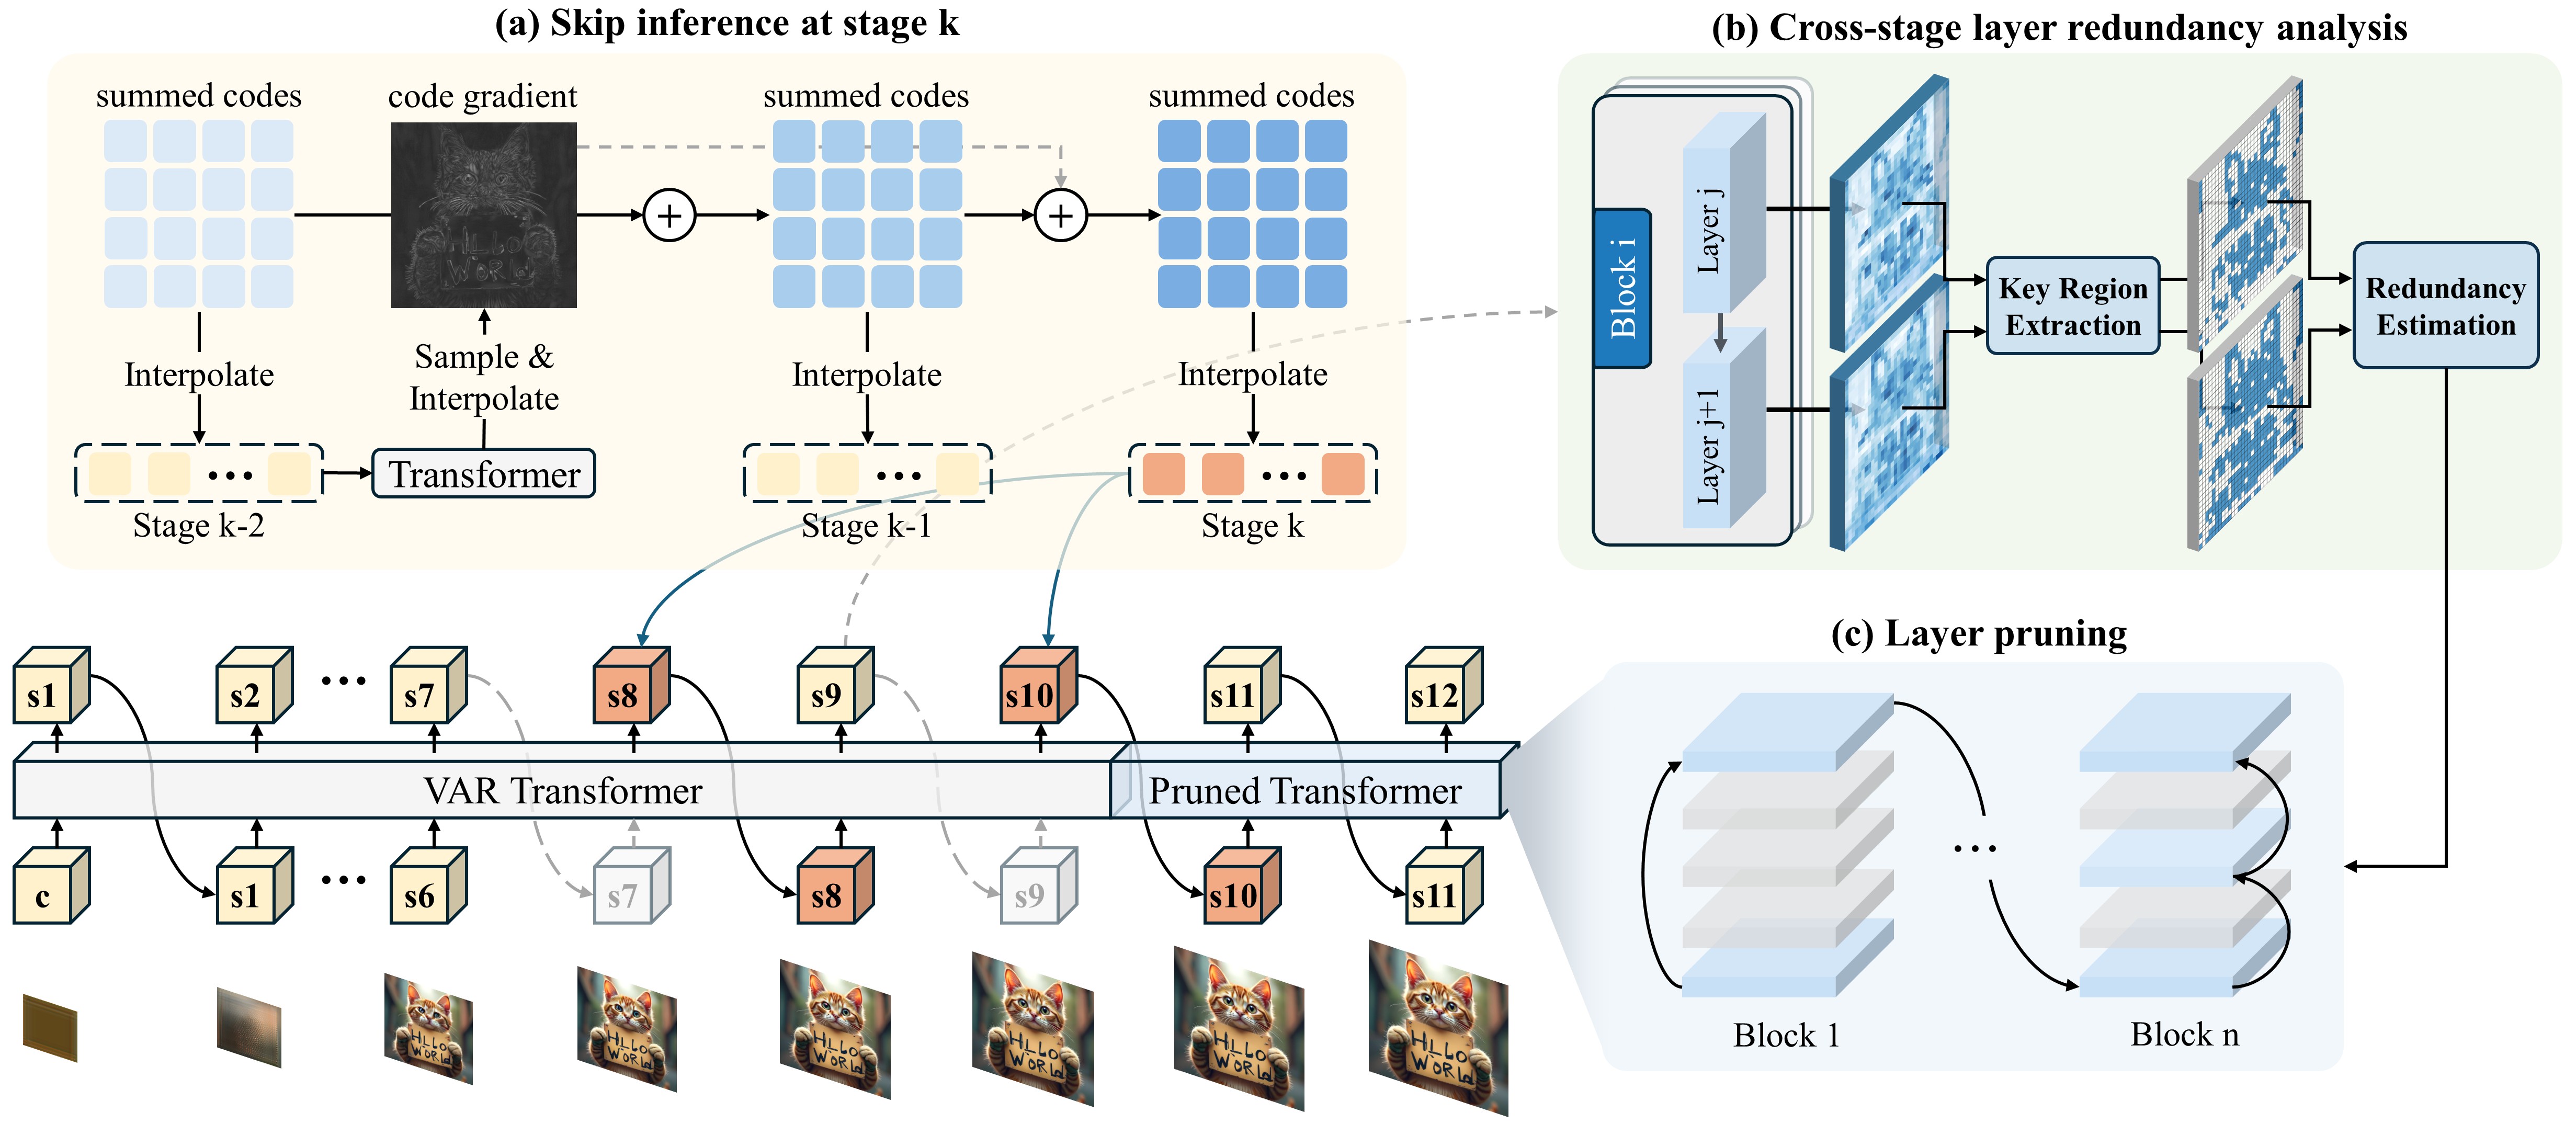
Overview of the proposed PruneVAR method. Subfigure (a) illustrates the cache-then-prune strategy in the structure-stabilization stage SS, where model inference alternates with reuse of cached outputs. Subfigure (b) shows the process of identifying redundant layers by analyzing overlapping modification regions across adjacent layers. Subfigure (c) demonstrates the application of the identified redundant layers to perform layer pruning during the quality refinement stage QR.
Results
Infinity
HART
 |
 |
 |
 |
|---|---|---|---|
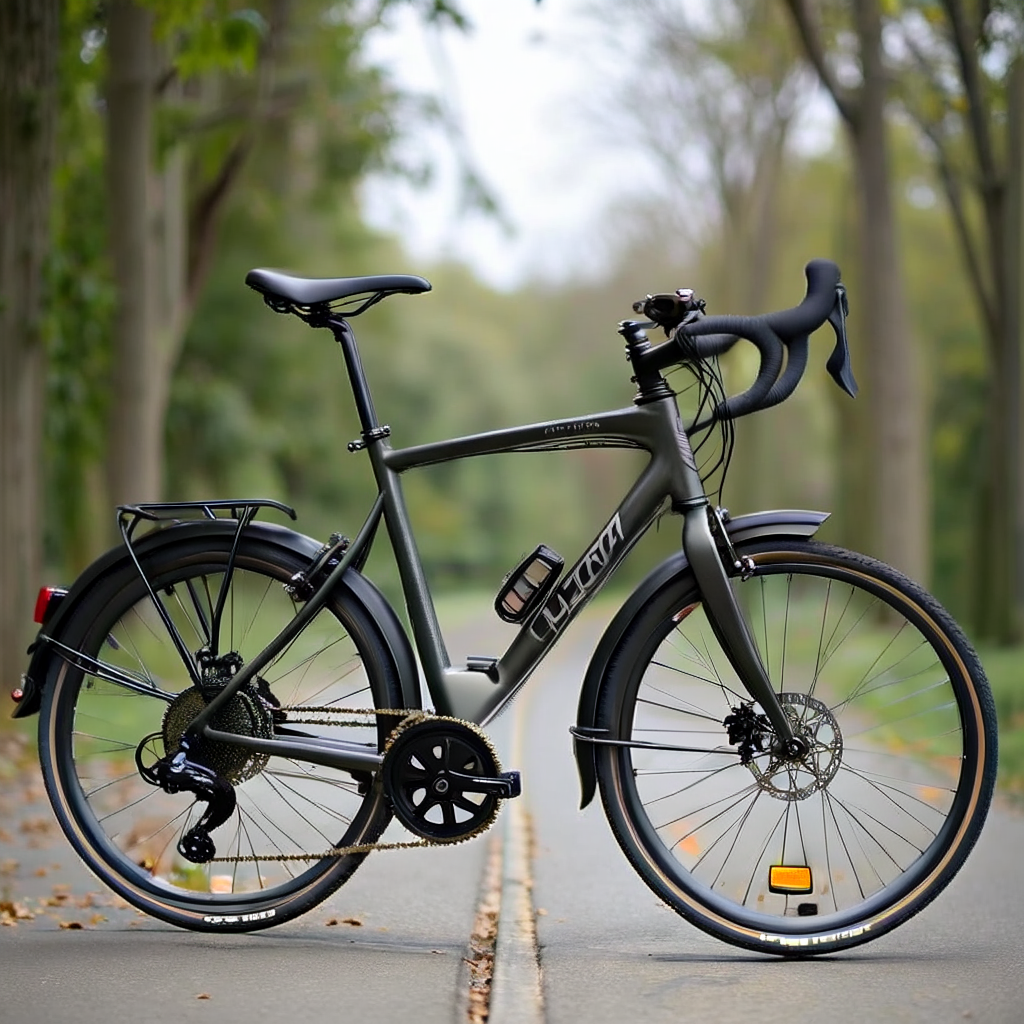
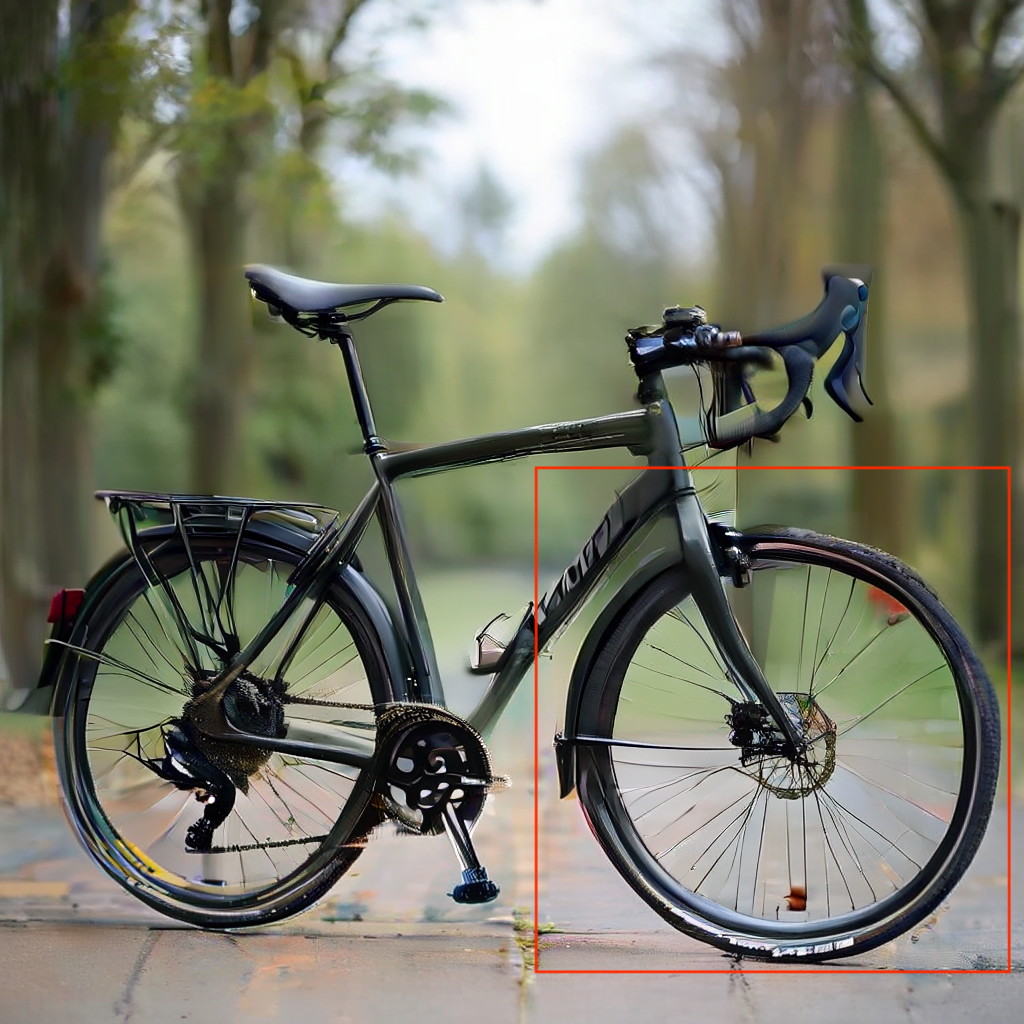
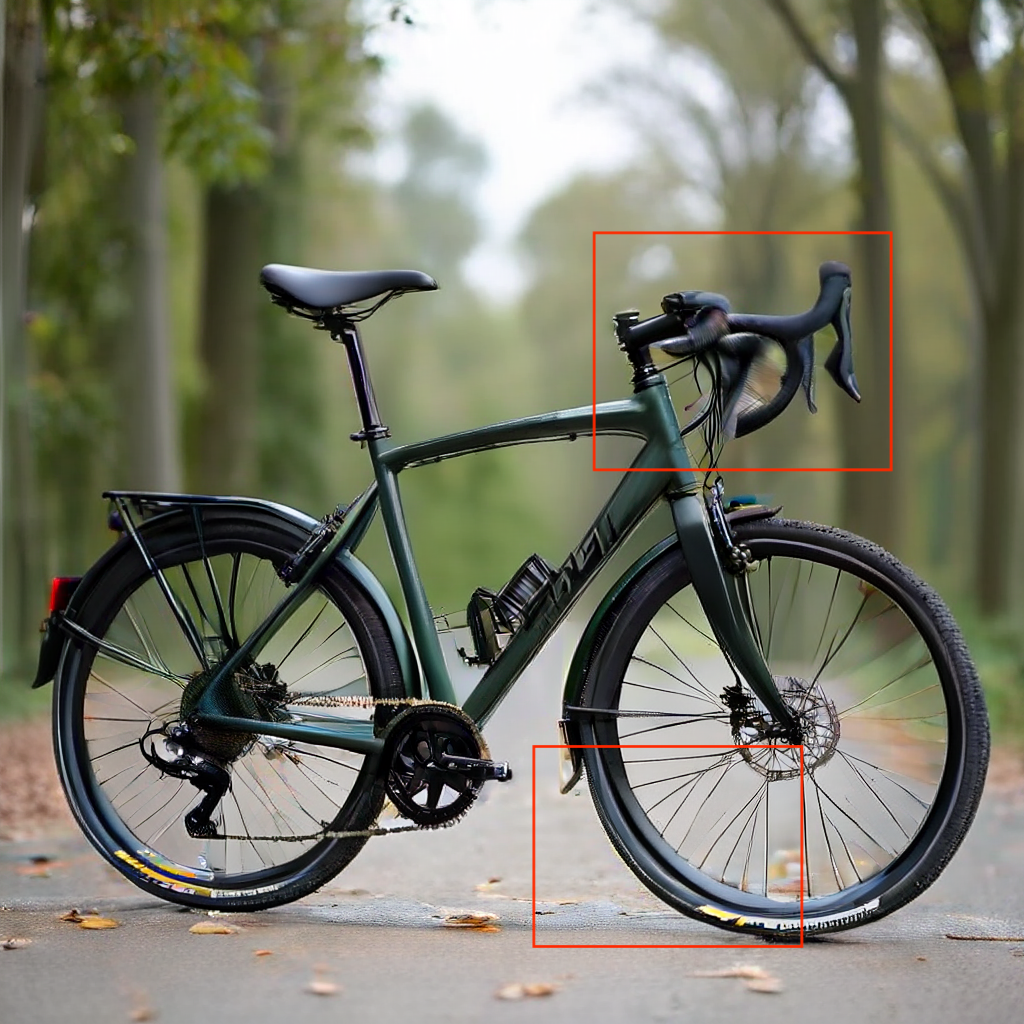
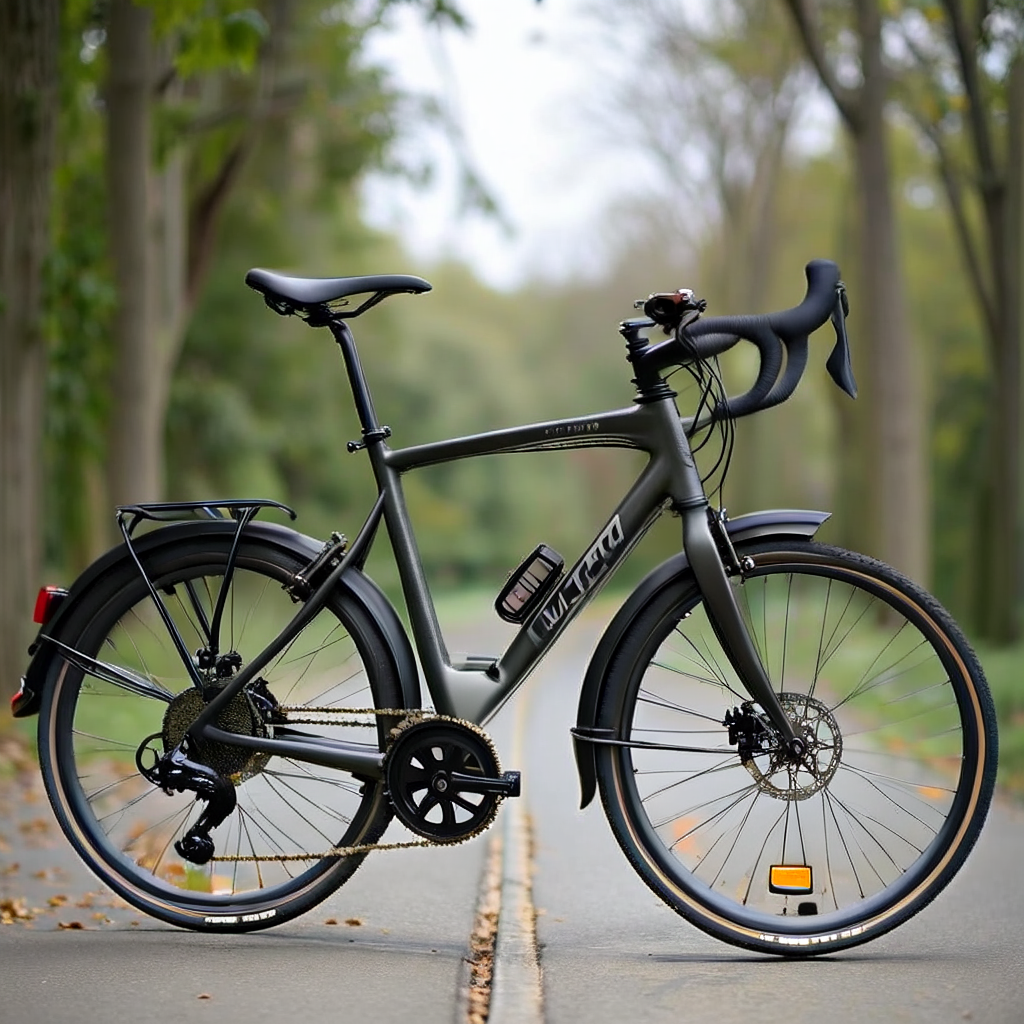
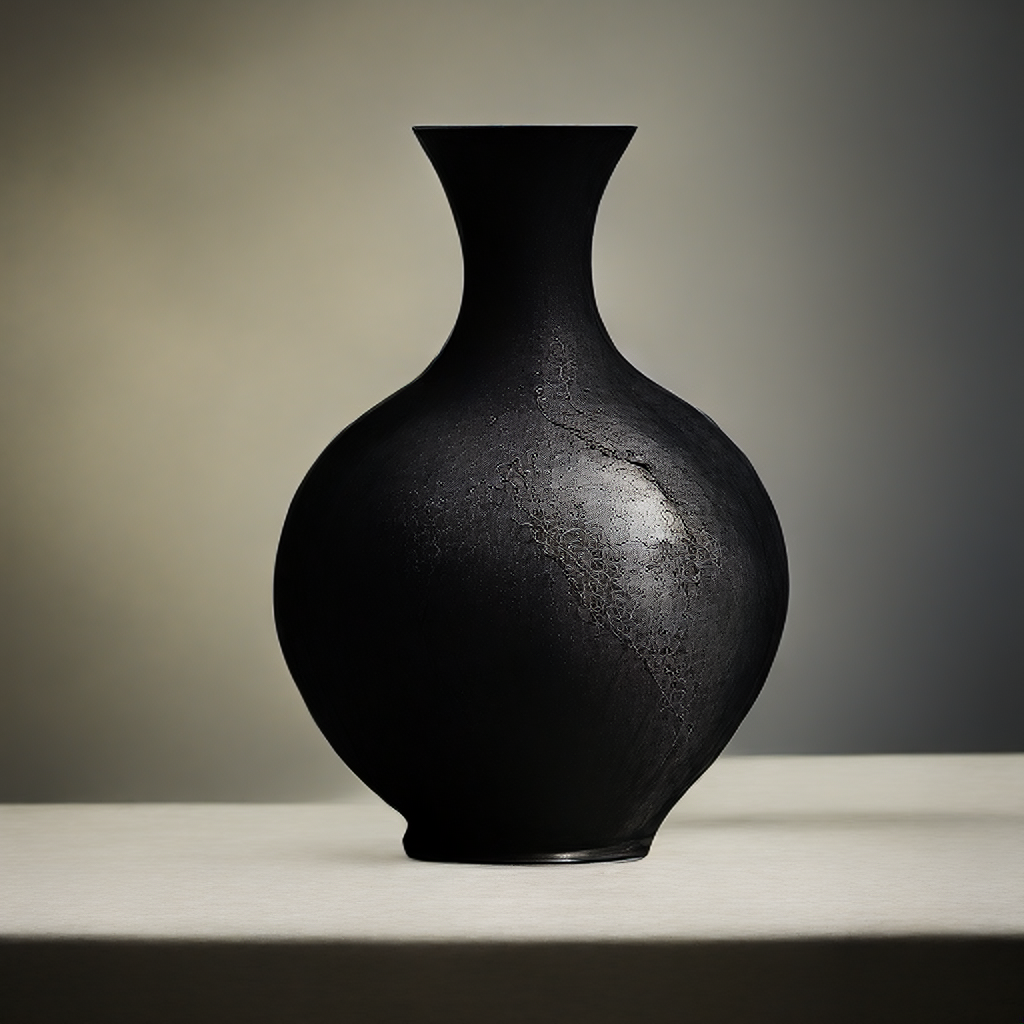
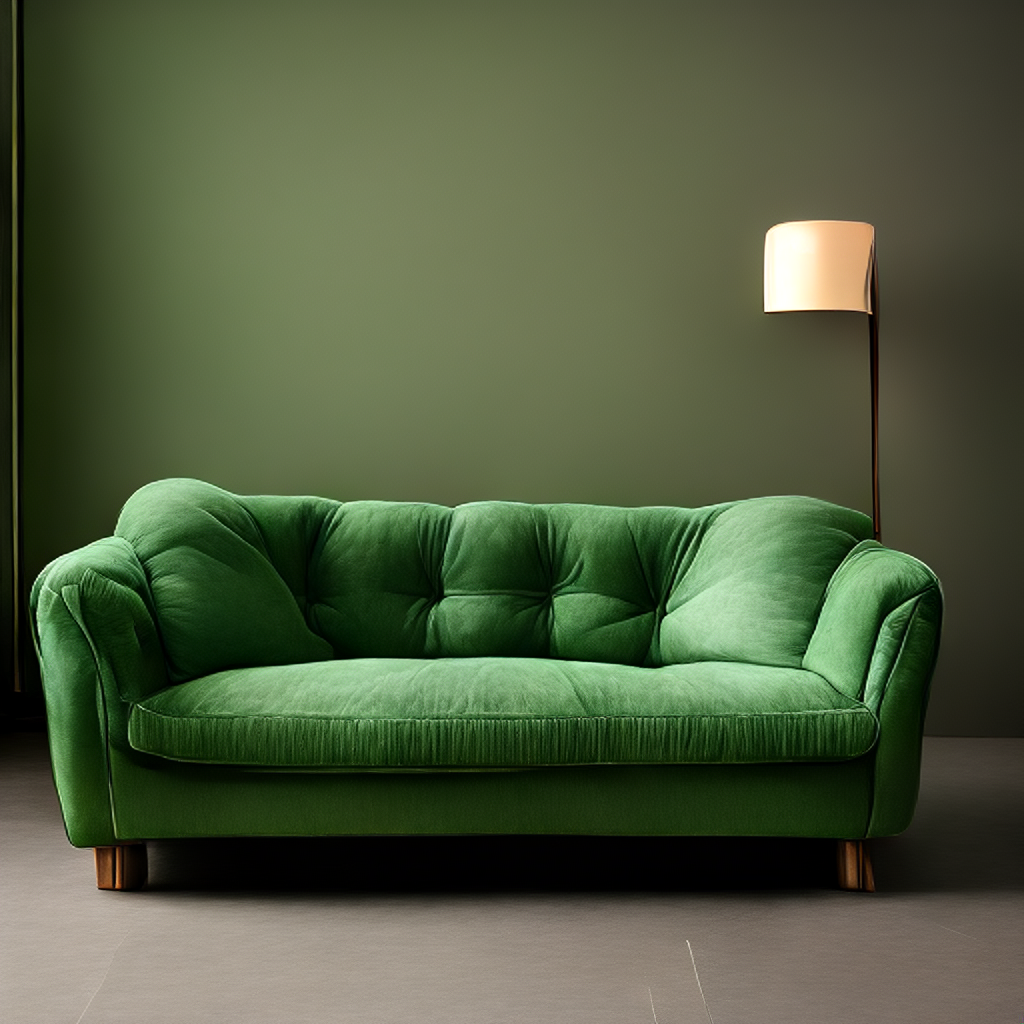
Origin (0.903s) |
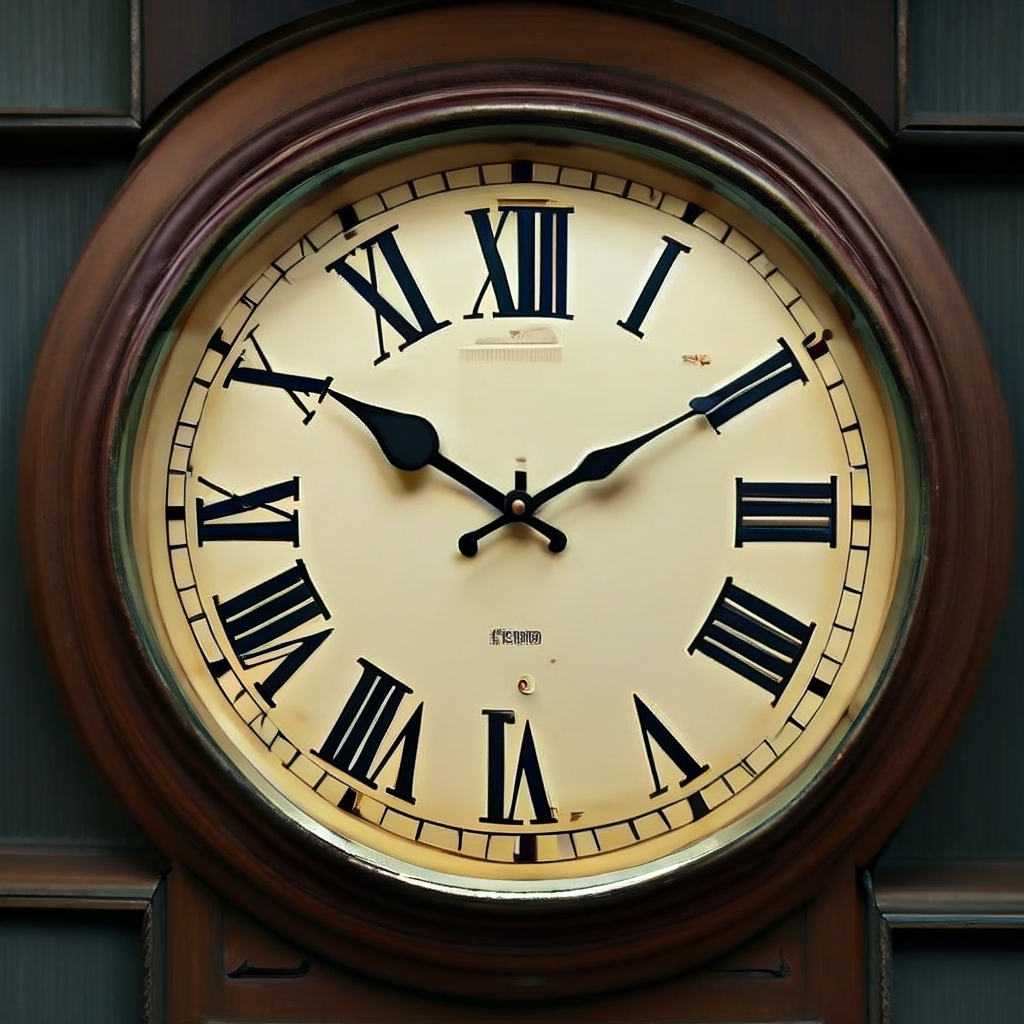
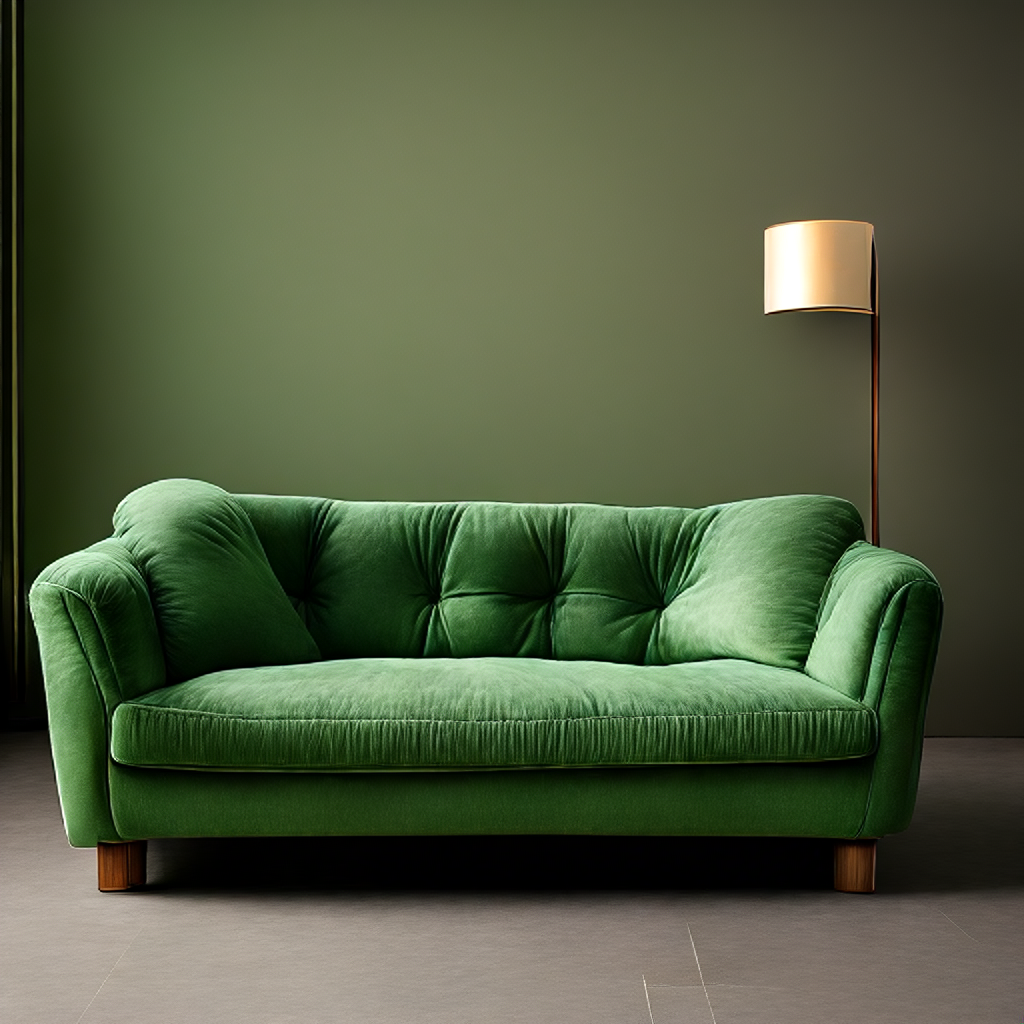
FastVAR (0.651s) |
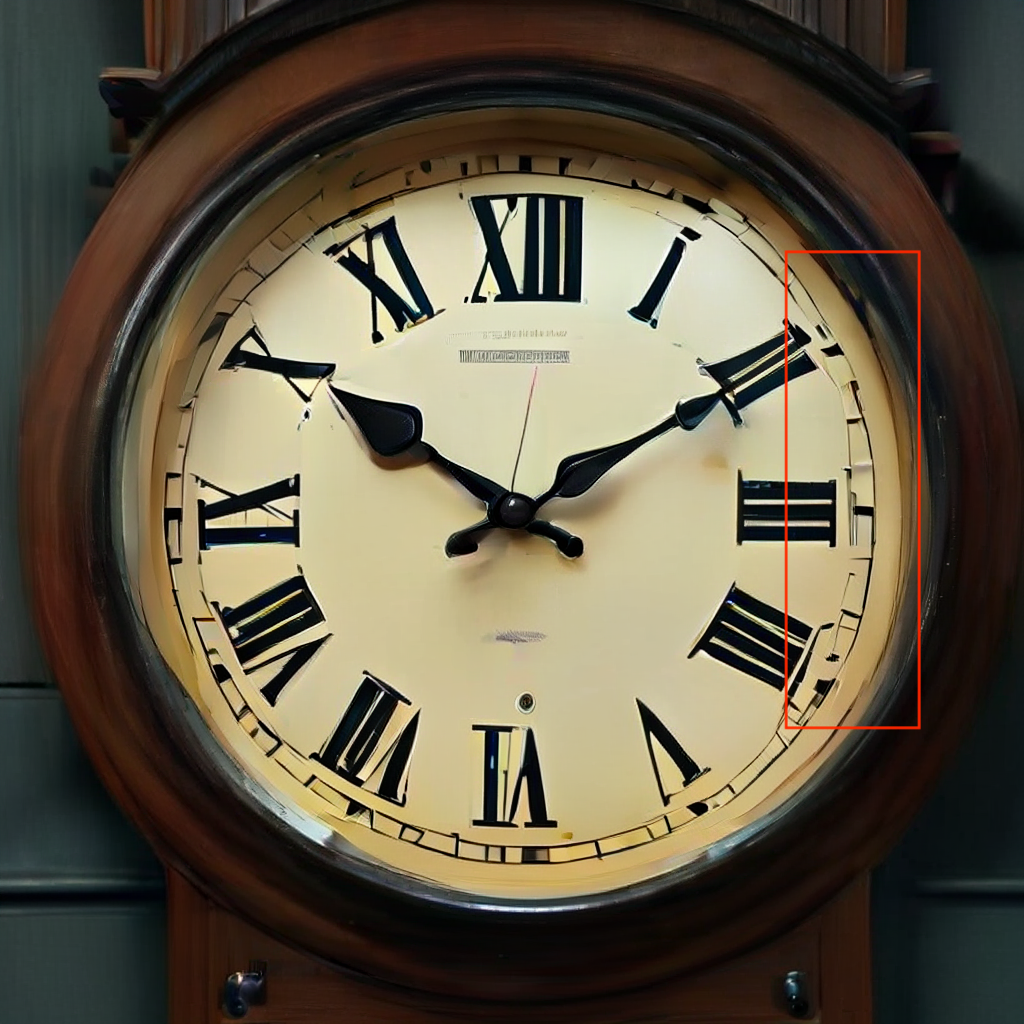
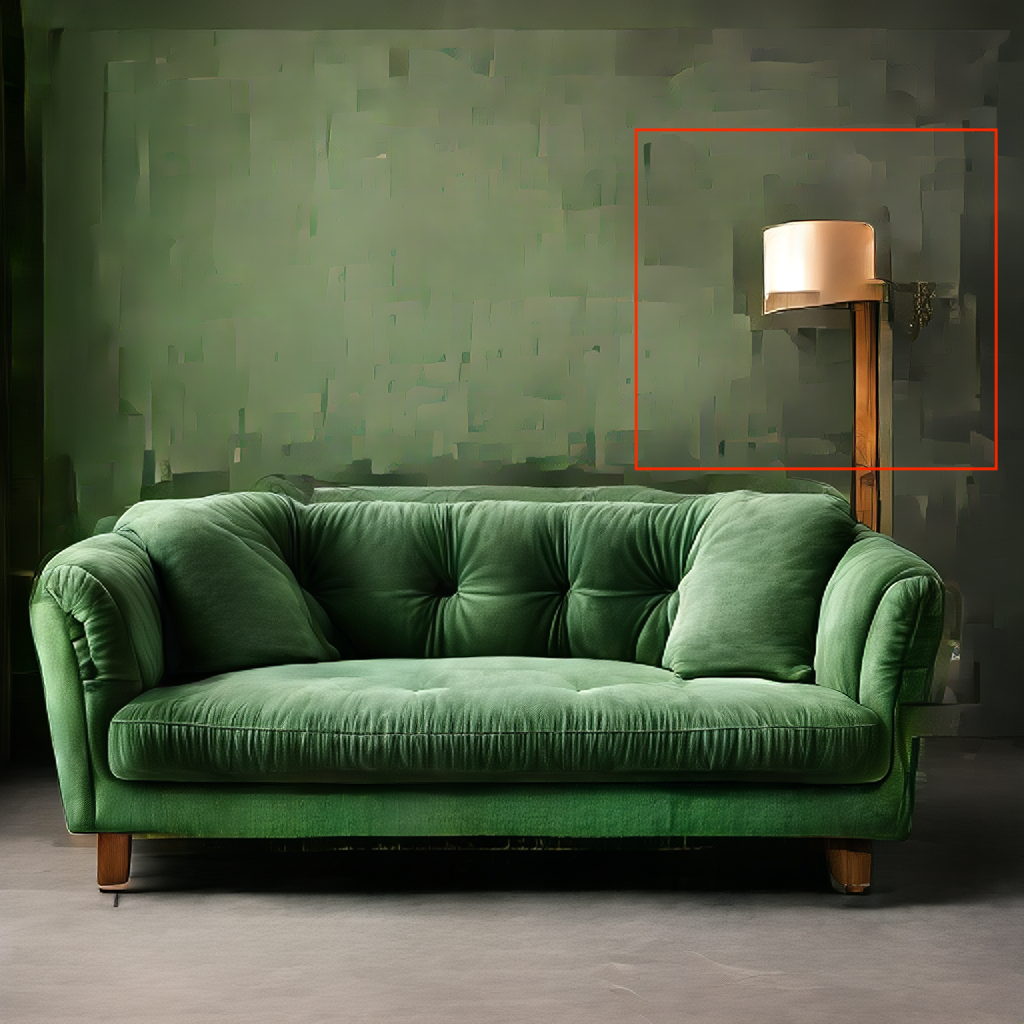
SparseVAR (0.682s) |
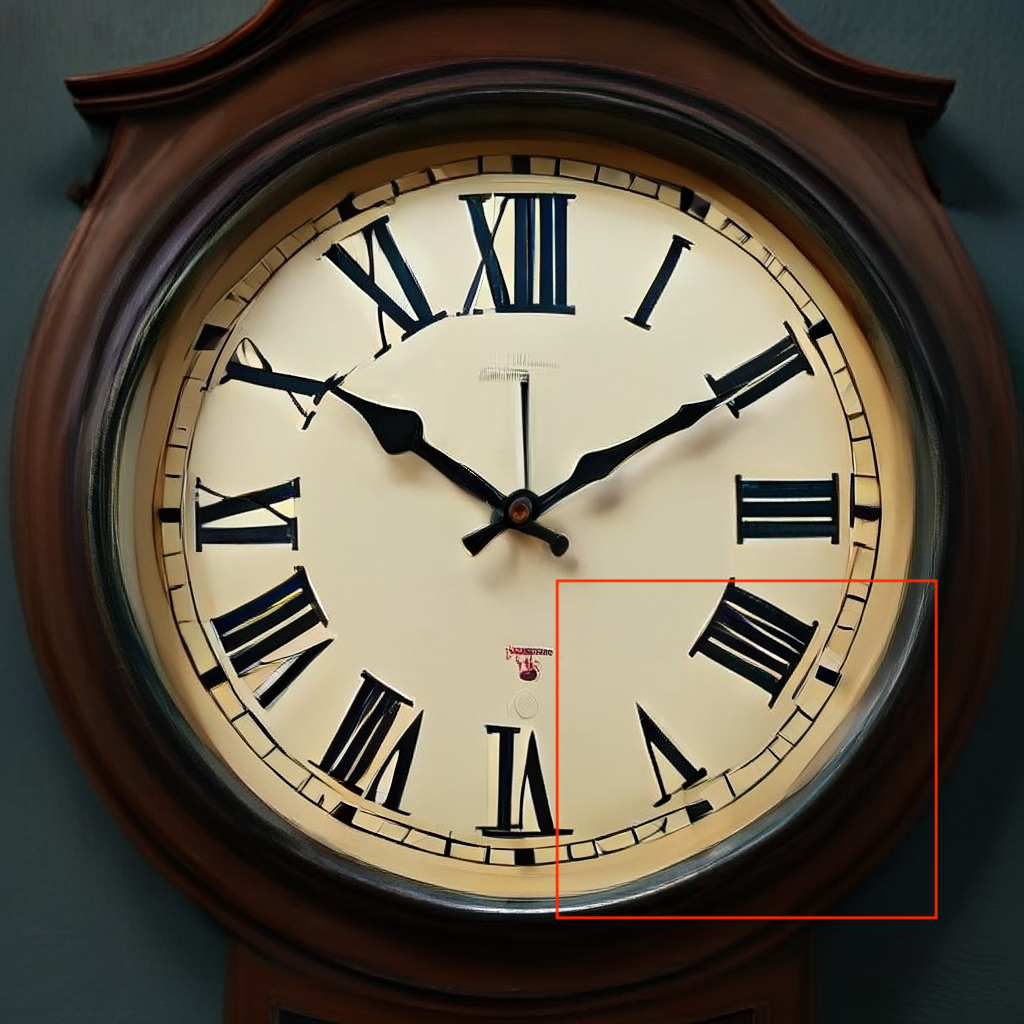
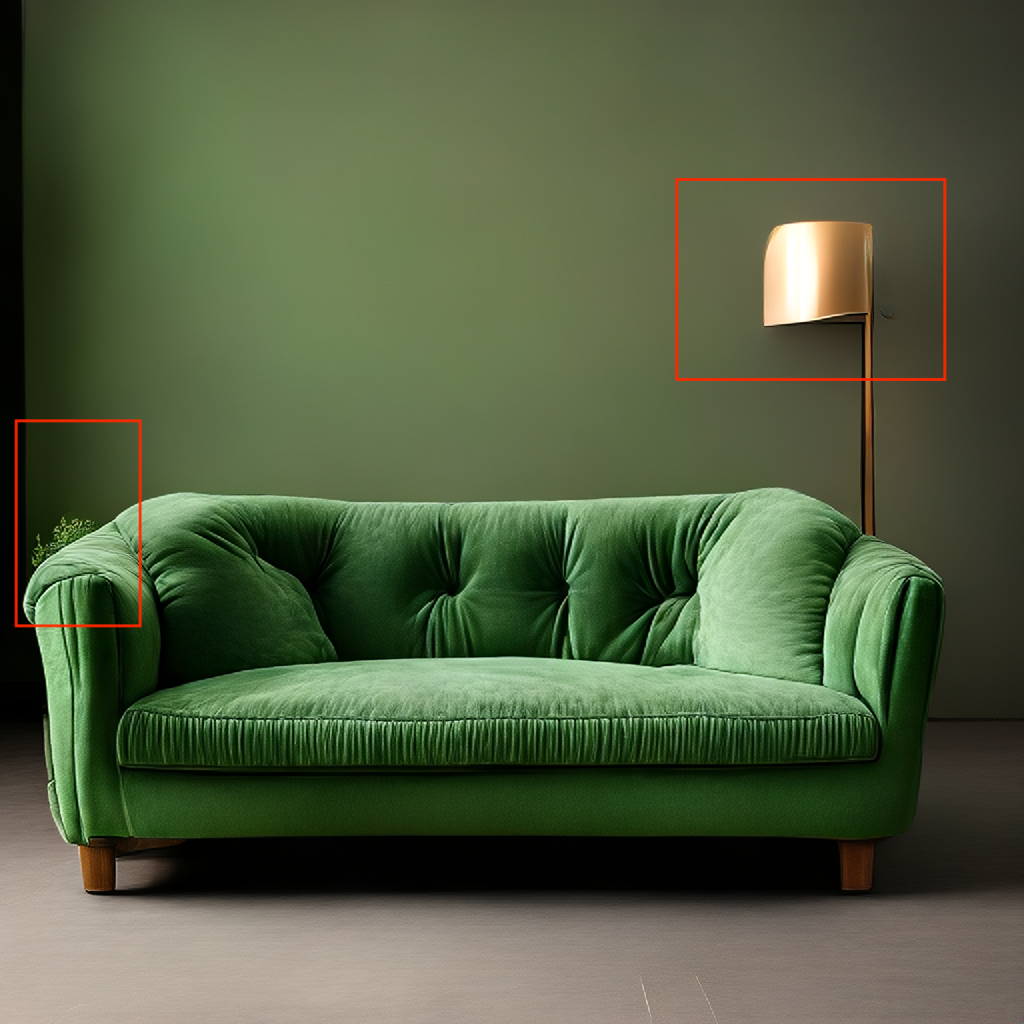
PruneVAR (0.651s) |
 |
 |
 |
 |
|---|---|---|---|
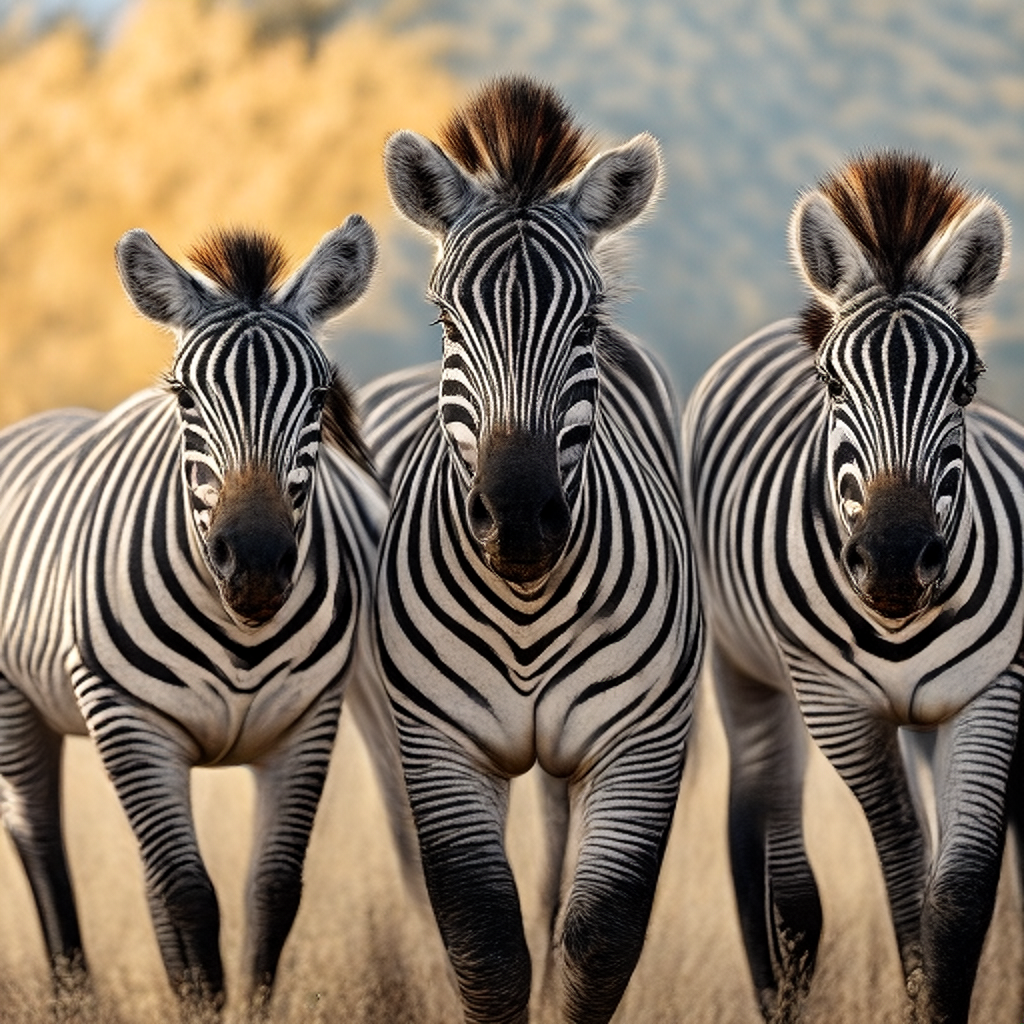
Origin (0.932s) |
FastVAR (0.662s) |
SparseVAR (0.678s) |
PruneVAR (0.659s) |
 |
 |
 |
 |
|---|---|---|---|
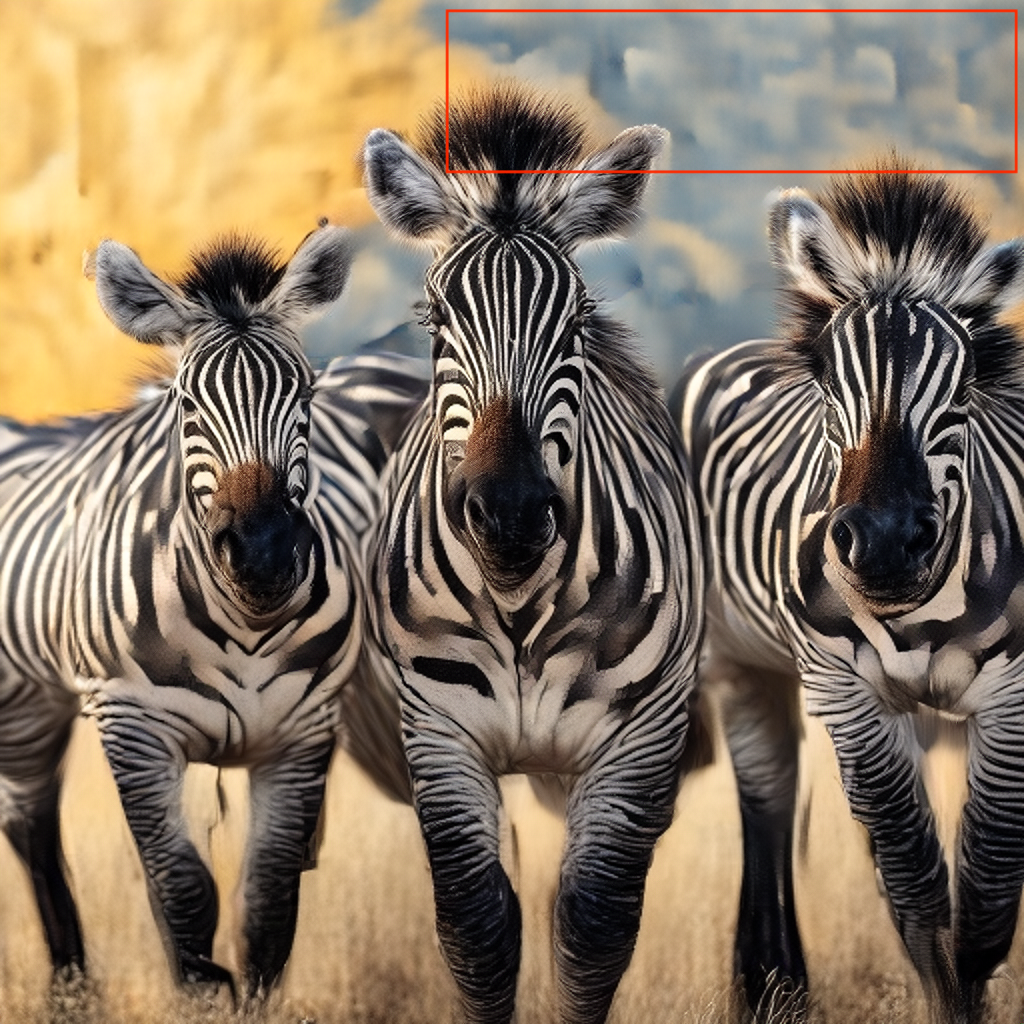
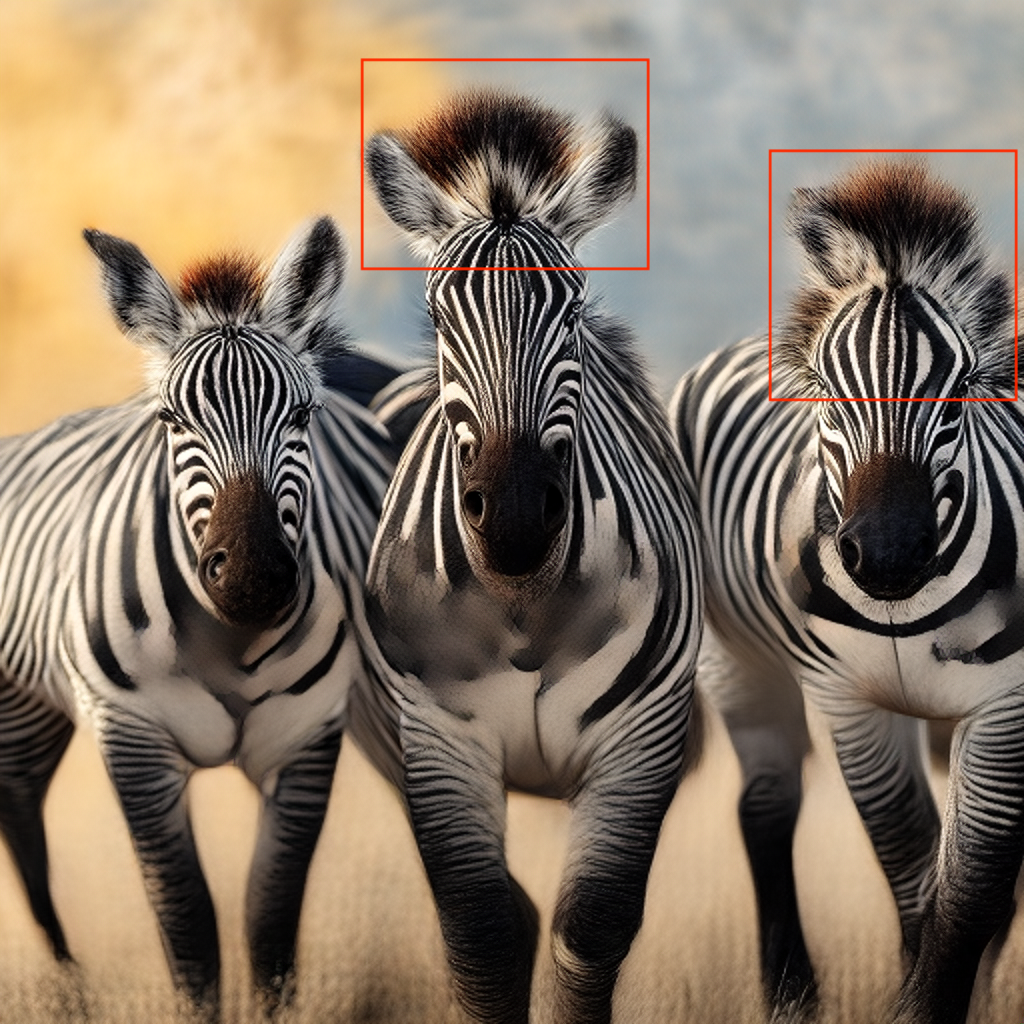
Origin (0.898s) |
FastVAR (0.653s) |
SparseVAR (0.649s) |
PruneVAR (0.654s) |